At some point, every serious football bettor asks the same question: can I build a model that predicts match outcomes better than the sportsbook? The honest answer is that beating the sportsbook’s model is extremely difficult — they have teams of quantitative analysts, proprietary data feeds, and decades of institutional knowledge. But you do not need a better model than the sportsbook to profit. You need a model that identifies specific situations where the sportsbook’s output is slightly wrong, and you need the discipline to bet only in those situations.
Building a football betting model is not about creating a crystal ball. It is about creating a structured framework that converts data into probability estimates, compares those estimates to the market’s prices, and flags discrepancies worth betting on. The model does not need to be sophisticated. A basic Poisson model built in a spreadsheet can identify value that the naked eye misses. What matters is the process: systematic, repeatable, and grounded in data rather than intuition.
Utilizing the Poisson Distribution Model
The Poisson distribution is the most widely used statistical foundation for football betting models. It models the probability of a given number of events (goals) occurring in a fixed interval (a match), based on an average rate of occurrence.
The core input is each team’s expected goals for a specific match. You derive this from their season-long attacking and defensive records, adjusted for the opponent. If Team A averages 1.6 goals scored per match and Team B averages 1.3 goals conceded per match, you can estimate Team A’s expected goals in this fixture by combining these rates relative to the league average.
The standard calculation uses attack strength and defense strength ratios. Attack strength = Team’s goals scored per match / League average goals scored per match. Defense strength = Team’s goals conceded per match / League average goals conceded per match. Expected goals for Team A = Team A’s attack strength × Team B’s defense strength × League average goals per match.
Suppose the league averages 1.4 goals per home team per match. Team A (home) has scored 1.8 per match at home (attack strength = 1.8/1.4 = 1.286). Team B (away) has conceded 1.5 per match away (defense strength = 1.5/1.4 = 1.071). Team A’s expected goals = 1.286 × 1.071 × 1.4 = 1.93.
Run the same calculation for Team B’s expected goals against Team A’s defense, and you have two lambda values — one for each team. The Poisson formula then gives you the probability of each team scoring 0, 1, 2, 3, 4, or 5+ goals. Multiplying the individual goal probabilities together produces a probability matrix for every possible scoreline, from 0-0 to 5-5 and beyond.
From this matrix, you can derive the probability of any betting outcome: home win (sum of all cells where home goals exceed away goals), draw (sum of the diagonal), away win (sum of all cells where away goals exceed home goals), over/under any total, BTTS yes/no, correct score, and more. A single Poisson model powers analysis across virtually every football betting market.
Sourcing and Preparing Your Data
A model is only as good as the data feeding it. Fortunately, football data for model building is abundant and largely free.
FBref provides match-level and team-level statistics for major leagues worldwide. It originally offered advanced data powered by StatsBomb, then switched to Opta in 2022, but lost all advanced statistics in January 2026 after a dispute with its data provider. It remains useful for basic historical results and squad data, but for xG and other advanced metrics, bettors should now turn to alternatives like Understat, FotMob, or WhoScored.
Football-Data.co.uk maintains historical results and odds data for dozens of leagues going back to the 1990s. The datasets include match results, goals scored, shots, corners, cards, and closing odds from multiple sportsbooks. This historical data is invaluable for backtesting your model — checking whether it would have been profitable if applied to past seasons.
Understat offers xG data with shot-level granularity for six European leagues — the top five (Premier League, La Liga, Bundesliga, Serie A, Ligue 1) plus the Russian Premier League. The ability to access individual shot data lets you build custom xG models or validate your Poisson inputs with more precise chance-quality metrics.
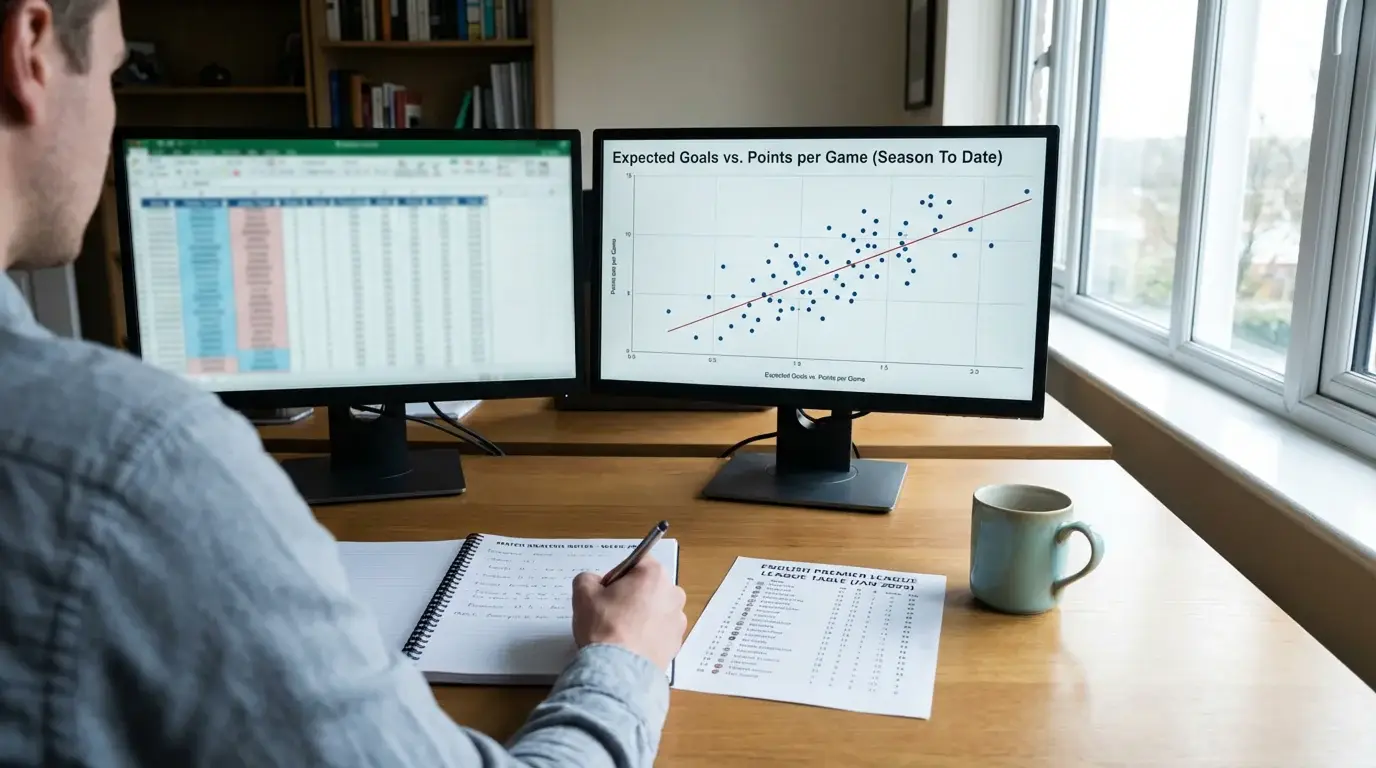
To make your predictive algorithms more accurate, you must integrate an expected goals (xG) model into your baseline calculations.
Data preparation involves cleaning the raw data, calculating the attack and defense strength ratios described above, and splitting records into home and away performance. Home and away splits matter because most teams perform differently at home versus away, and a model that ignores this distinction will be less accurate than one that accounts for it.
A common mistake is using only the current season’s data. Early in a season, sample sizes are too small for reliable averages. A practical approach is to weight the previous season’s data heavily in August and September, gradually shifting toward current-season data as more matches are played. By December, the current season’s data is usually sufficient on its own.
Testing Your Model’s Accuracy
A model that has never been tested against historical data is a hypothesis, not a tool. Backtesting — applying your model to past matches and checking whether its predictions were accurate and profitable — is an essential step before risking real money.
The simplest backtest involves running your model on the previous season’s data, generating match-by-match probability estimates, and comparing those estimates to the actual results. You are looking for two things: calibration and profitability.
Calibration means that when your model assigns a 60% probability to an outcome, that outcome occurs approximately 60% of the time across a large sample. If your 60% predictions actually win 50% of the time, the model is overconfident and needs adjustment. If they win 70% of the time, the model is underconfident and you are leaving value on the table. Plot your predicted probabilities against actual outcomes in buckets (50-55%, 55-60%, etc.) and check whether the relationship is close to the diagonal. A well-calibrated model should track the diagonal closely.
Profitability means that when your model identifies a discrepancy between its probability and the sportsbook’s implied probability, betting on the model’s side produces a positive return over the sample. This is the ultimate test: does the model find genuine mispricing, or does it merely identify the same probabilities the sportsbook already priced in? If your model consistently matches the closing line’s implied probability without improving on it, the model is accurate but not profitable — it is simply reproducing the market’s consensus.
A critical backtest principle: never test on the same data you used to build the model. If you derived your attack and defense strength ratios from the 2024-25 season and then test the model on the same season, the results will be artificially good. Use one season to calibrate and a different season (or the second half of the same season, using only first-half data for inputs) to test.
Elo Ratings: An Alternative Approach
The Poisson model is not the only framework for football prediction. Elo ratings — originally developed for chess — offer a different approach that some bettors prefer for its simplicity and adaptability.
An Elo system assigns each team a numeric rating that increases after wins and decreases after losses. The magnitude of the adjustment depends on the strength of the opponent and the margin of victory. Beating a highly rated team produces a larger Elo gain than beating a weak one. Losing to a weak team produces a larger drop than losing to a strong one.
The betting application of Elo ratings is straightforward: the difference in Elo ratings between two teams can be converted to a win probability using a logistic function. A team rated 1600 facing a team rated 1500 might have a calculated 64% chance of winning, depending on the specific parameters of the Elo system. If the sportsbook implies a 58% chance for the same team, the model suggests a value bet.
Elo’s advantage over Poisson is that it naturally accounts for opponent quality and recent form, since the ratings update after every match. Its disadvantage is that it does not directly model goal-scoring distributions, which means deriving correct-score, totals, or BTTS probabilities from an Elo system requires additional modeling steps that the Poisson framework handles natively.
Many successful bettors use hybrid approaches: Elo ratings for estimating match-result probabilities and Poisson distributions for market-specific pricing (totals, BTTS, correct score). The two frameworks complement each other because they capture different aspects of team performance.
Comparing Model Outputs to Bookmaker Odds
The final step in the model-building process is the one that determines whether you have a betting tool or an academic exercise: comparing your probability estimates to the sportsbook’s prices and identifying actionable discrepancies.
Convert the sportsbook’s odds to implied probabilities and set them alongside your model’s output. If your model says home win at 55% and the sportsbook implies 50%, the home side may offer value. If your model says 51% and the book implies 50%, the discrepancy is within the margin of error and not worth betting.
A practical threshold is to require at least a 3-5% edge — meaning your model’s probability exceeds the implied probability by at least 3 to 5 percentage points — before placing a bet. This buffer accounts for the uncertainty in your own model and the sportsbook’s margin. Over time, as you gain confidence in your model’s calibration, you can narrow this threshold.
The Model Is Never Finished
Building a football betting model is not a project with a completion date. It is an ongoing process of refinement, testing, and adaptation. Leagues change, teams change, tactical trends evolve, and the sportsbook’s own models improve constantly. A model that identified value last season might not find the same edges this season because the market has adjusted.
The bettors who profit from models over long periods are the ones who treat the model as a living system — updating inputs, recalibrating parameters, testing new features, and honestly evaluating performance. They accept that the model will be wrong often, that profitable seasons will alternate with breakeven or losing ones, and that the edge is always thin enough that complacency destroys it.
What the model gives you, more than any specific bet, is a process. A structured, repeatable way of evaluating football matches that does not depend on gut feeling, media narratives, or the illusion that you can predict the future. You cannot predict the future. But you can estimate probabilities more accurately than the market in specific, identifiable situations — and a model is the tool that helps you find those situations before the kickoff whistle blows. Refine your data analysis techniques using the comprehensive tools found at our trusted football betting portal.
